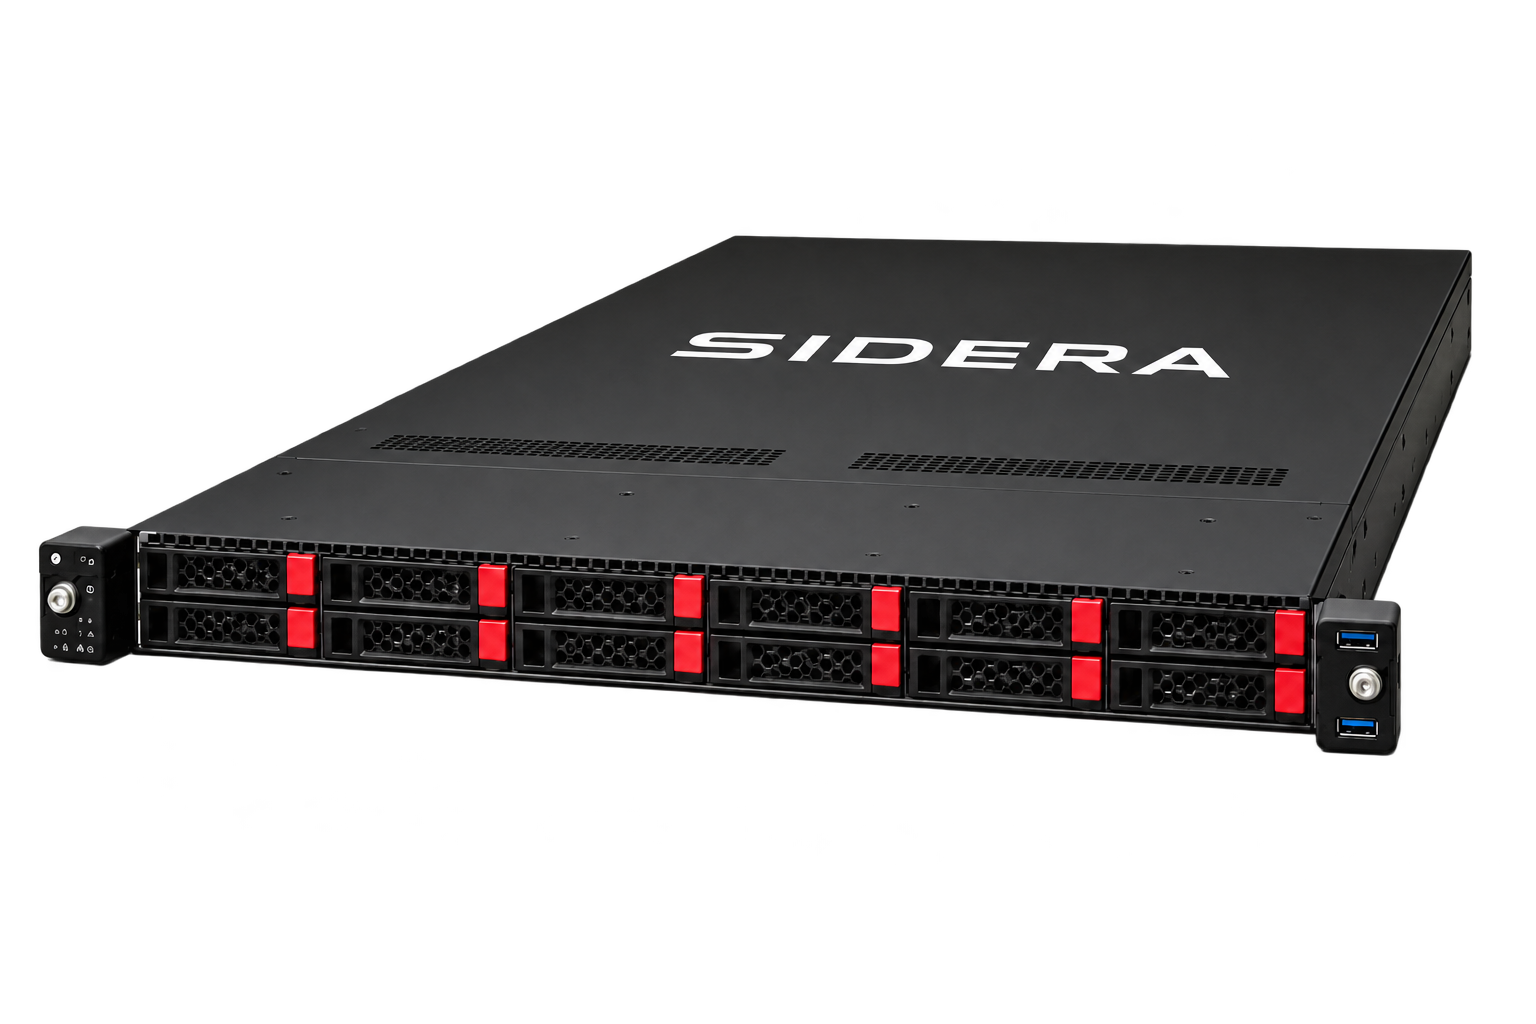
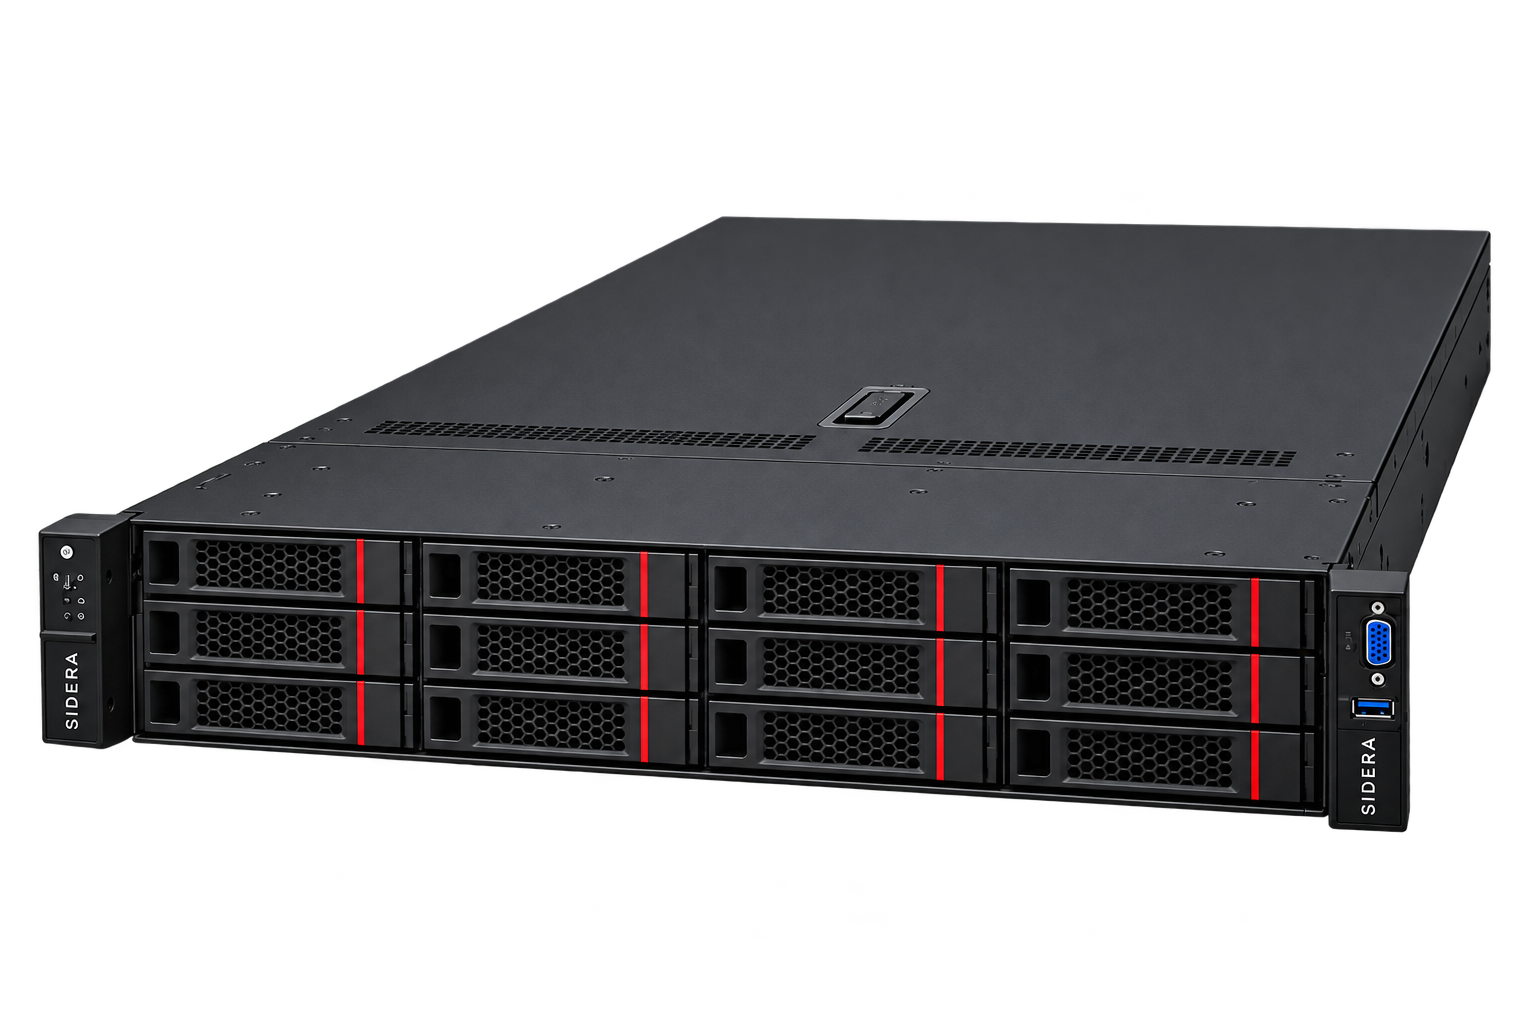
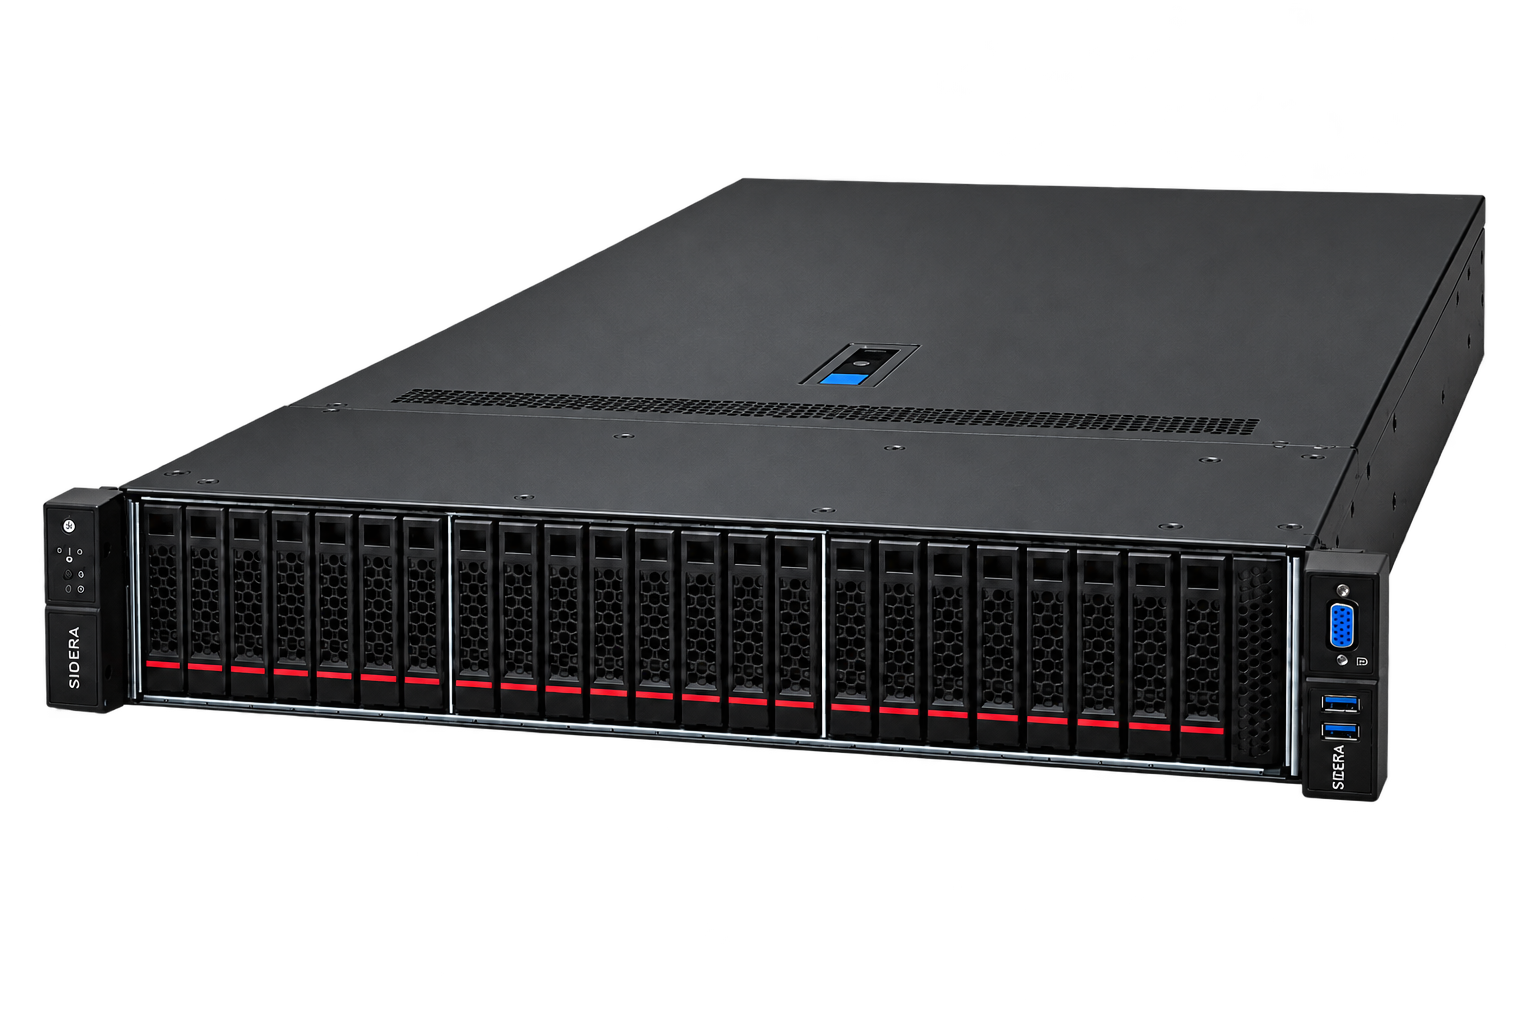
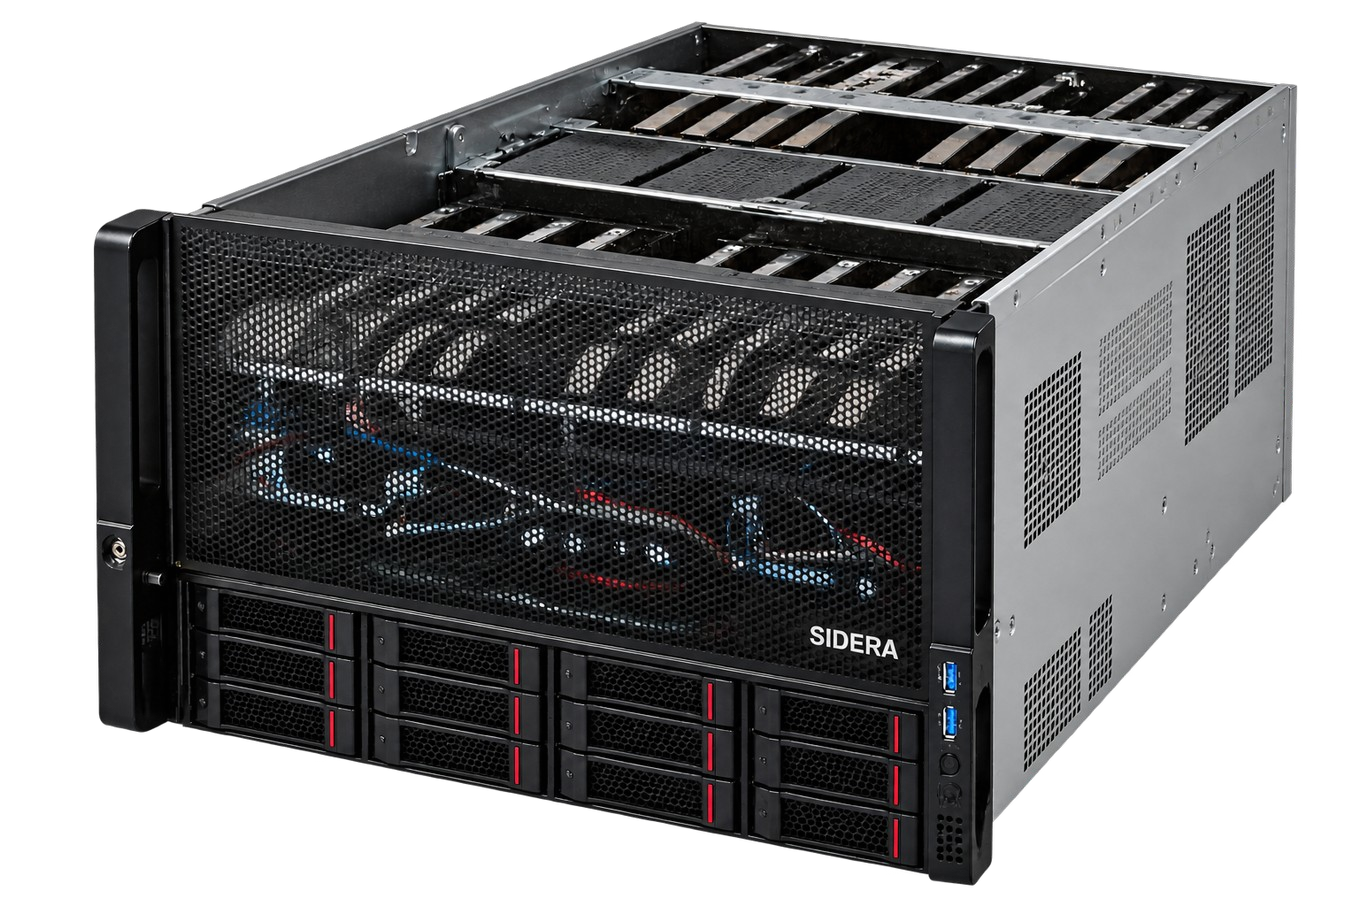
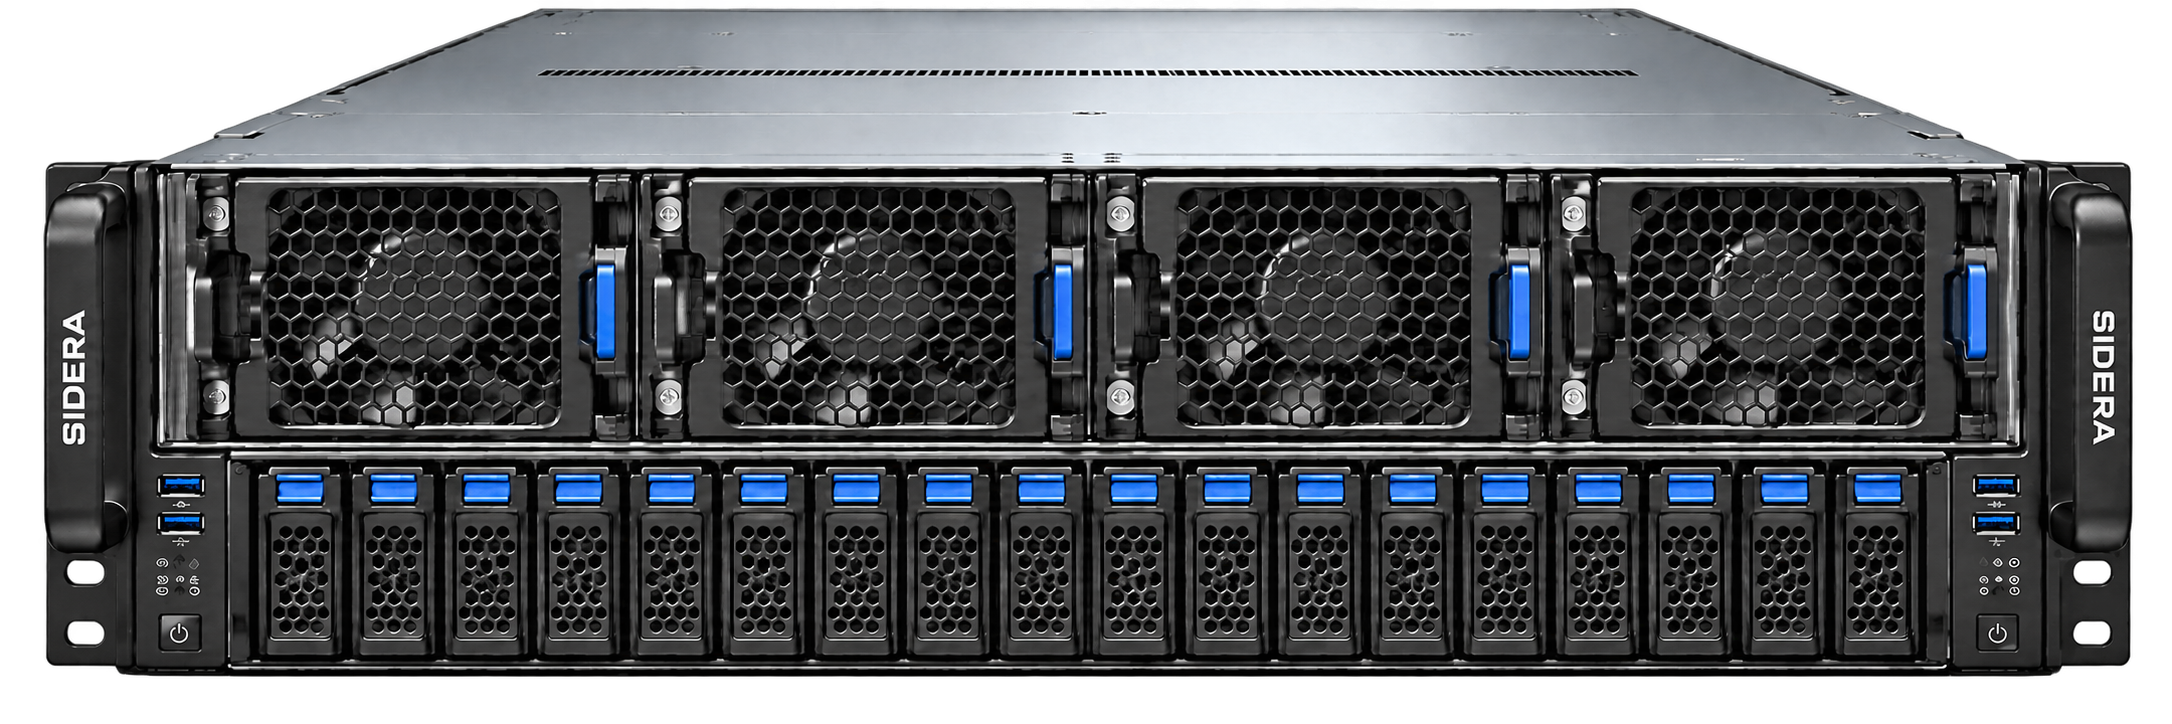
Dense compute server
A compact platform for virtualization, application services, database nodes and scale-out clusters.
- 2 × Intel® Xeon® 6
- 32 DDR5 ECC RDIMM slots
- 12 front SFF bays
- Up to 2 HHHL PCIe cards
Configuration and availability on request
Enterprise & AI servers
From enterprise compute and data systems to GPU-accelerated platforms, SIDERA offers server configurations aligned with application requirements, expansion, networking, facility conditions and support expectations.
SIDERA server platforms are manufactured for SIDERA through an established, vertically integrated production environment with enterprise-server experience and a track record serving international technology brands. SIDERA localizes and configures each platform around the selected compute, storage, networking and expansion requirements. The applicable warranty route and support scope are confirmed for each order.
We work closely with the customer to configure each AI server around the workload, accelerator choice, facility constraints, qualification path and acceptance criteria.
Enterprise servers
For virtualization, enterprise applications, storage and data services, networking applications and general-purpose computing.

A compact platform for virtualization, application services, database nodes and scale-out clusters.
Configuration and availability on request

Balanced compute, storage and expansion for databases, VDI, backup, archive and security appliances.
Configuration and availability on request

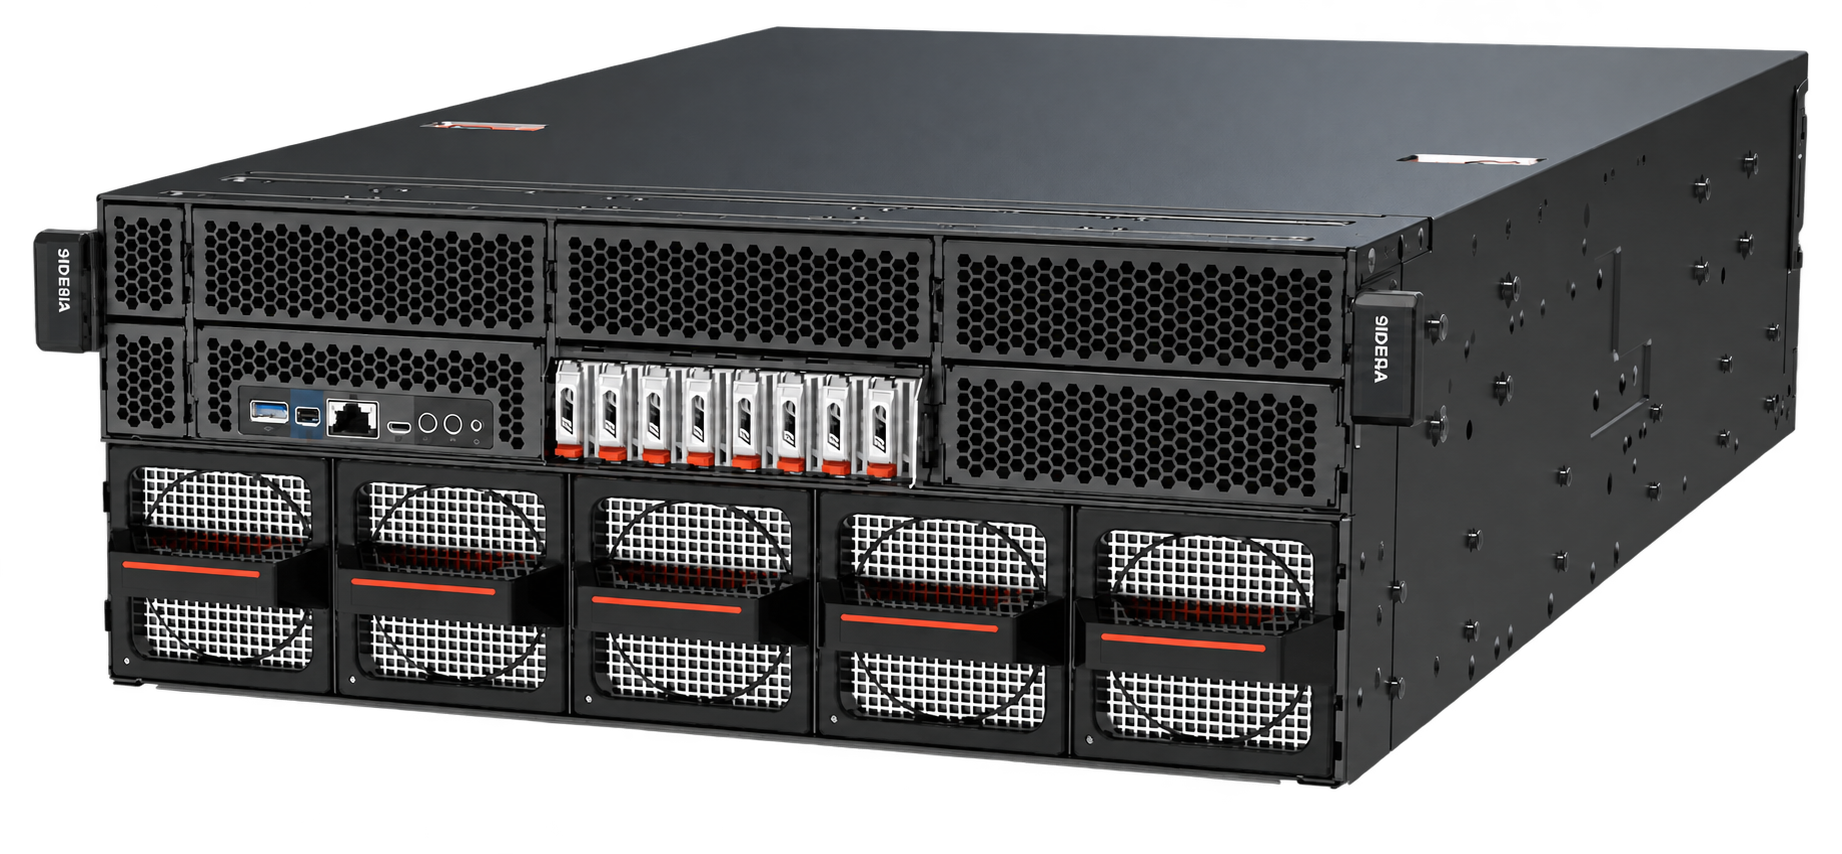
High-throughput data and accelerator platform for analytics, AI inference, video, caching and software-defined storage.
Configuration and availability on request

A project-configured GPU platform for AI training and inference, computer vision, rendering and HPC workloads.
Configuration and availability on request
Project-configured platforms for inference, model serving, fine-tuning, training where supported, computer vision and technical computing.
Pre-configured inference software
SIDERA pre-configures this software layer as an option for qualified NVIDIA GPU inference environments. It dynamically allocates capacity across realtime, batch and interactive workloads so the available GPU fleet can respond to changing demand more efficiently.
*Derived from ATOM’s 2× requests-within-SLA benchmark on the same 16-H100 fleet. This is not a universal cost-saving guarantee. Actual GPU requirements and economics depend on workload behavior, latency targets, topology, software compatibility and successful project qualification.
ATOM-reported benchmark results. SIDERA validates applicability on the customer’s workload before including the software and any expected capacity benefit in a final configuration.

An air-cooled platform for long-context inference, governed RAG, reasoning models, private model hosting and selected fine-tuning.
Reference configuration · availability on request

A balanced PCIe acceleration platform for enterprise inference, governed RAG, multimodal and visual AI, digital twins and private model hosting.
Reference configuration · availability on request

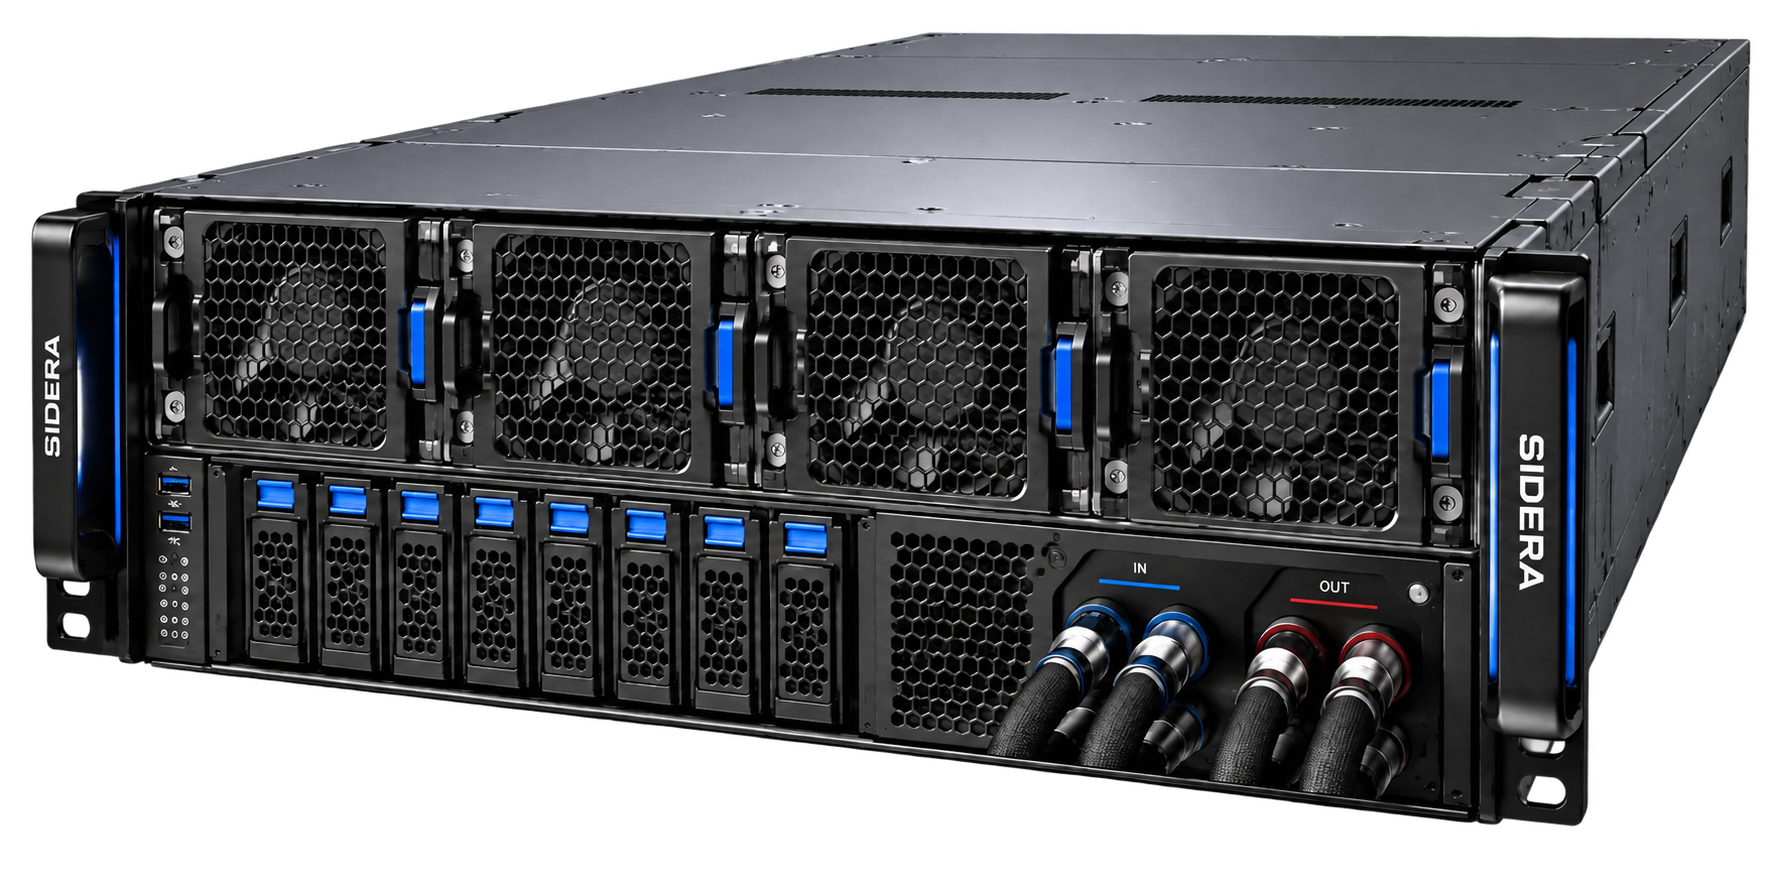
A liquid-cooled HGX platform for large-model training, fine-tuning, distributed inference, scientific workloads and multi-node scale-out.
Reference configuration · availability on request
Accelerator quantity, topology, networking, power, cooling, firmware, software compatibility, warranty and support responsibility are confirmed for the selected configuration. Component branding does not by itself establish certification of the complete server or rack.
Server configuration support
Product selection · Configuration review · Project-defined scope